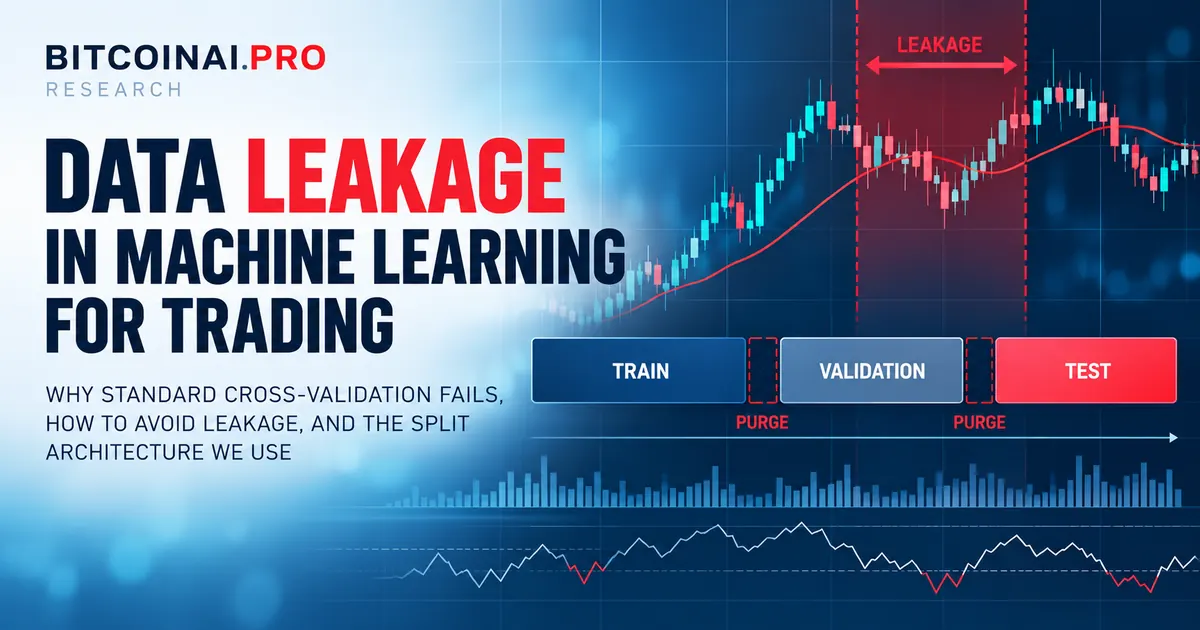
Data leakage in machine learning for trading is the failure that produces the most convincing wrong answers. Overfitting at least announces itself when the out-of-sample number arrives; leakage corrupts the out-of-sample number too, so the model looks excellent right up until it meets the market.
This article covers the mechanism, the correct split architecture, and six leakage patterns we have actually caught in our own pipeline — several of them after they had already produced results we believed.
Why standard cross-validation breaks on financial data
Ordinary k-fold assumes observations are independent and interchangeable. Financial observations are neither, and they fail in three separate ways.
Serial correlation. Adjacent bars share information. A random shuffle places nearly identical rows on both sides of the split, and the model is effectively tested on data it trained on.
Label overlap. This is the big one, and it is specific to how trading labels are constructed. With triple-barrier labelling, a trade opened on Monday may not resolve until Thursday. Its label is a function of Tuesday and Wednesday prices. If Monday sits in the training block and Wednesday in the test block, the training label contains information from the test period. No shuffling required — the leak is built into the label definition.
Non-stationarity. Volatility regimes, correlation structures and liquidity conditions drift. Randomly interleaved folds let the model learn each regime from both sides of a boundary, which is not a situation you will ever face live.
The fix: purging, embargoes and forward-only splits
Three corrections, in order of importance.
Forward-only splits. Every block is chronologically ordered: train, then validate, then test, never interleaved. Any design where the test data is earlier than some training data answers a question you will not be asked.
Purging. At every boundary, remove the observations whose labels resolve across it. Concretely: if your maximum holding period is H bars, delete the last H bars of the earlier block. This costs data and buys the right to believe the result.
Embargo. Beyond the purge, discard a further margin after the boundary to account for slower-moving effects — features with long lookbacks, volatility clustering that carries across the seam. Our practice is to set the gap wider than the maximum trade horizon rather than exactly equal to it.
This is where a small, frozen feature set pays for itself. A compact set of causally computed inputs makes it possible to audit every lookback, transformation and dependency at a split boundary. With dozens of features of uncertain provenance, validating the information flow becomes much harder and the risk of hidden leakage increases.
Our split architecture
Four chronological blocks, each with a purged boundary, each with a distinct job:
The block that matters most is the last one, and the rule protecting it is absolute: selection is always by validation; the test score of a trial chosen for its test score is not evidence. Sorting a results table by the test column and picking the winner converts your only virgin data into a second validation set. We have measured this precisely — candidates with mediocre validation and brilliant test scores share an ascending gradient toward the test block, which is exactly the signature of having won a lottery in the partition nobody selected on.
Six leakage patterns we have actually caught
Theory is cheap. These are from our own logs.
1. Label overlap across a boundary. The classic. Fixed by purging wider than the maximum holding period on every seam.
2. Structural spread artifacts harvested as signal. On one FX pair, a one-hour daily window carries spreads 20–50× normal — under a pip typically, nearly 29 pips observed live during rollover. The optimiser had found the mid-price behaviour in that window and built a system on it. Not leakage in the textbook sense, but the same category of error: the backtest had access to a price the market would never have given us. The window is now masked in every search.
3. Data-boundary sensitivity. A recorded test figure of 2.23 could not be reproduced on rebuild, coming out at 1.11. Twelve retrains ruled out non-determinism; sliding the partition across a whole quarter ruled out a simple boundary shift. The cause was how the original evaluation handled its data edge. The published figure is the reproducible one. If you cannot rebuild a number from a frozen artifact, you do not have the number.
4. Silent failures disabling protections. A dead-window mask that appeared to be active but was not, because the accelerated kernel — not the fallback path the patch had modified — was doing the work. Protections must fail loudly. We replaced silent exception handling with explicit sanity checks that abort the run.
5. Cross-run contamination. Shared cache keys that omitted a parameter, causing weights from a different configuration to be silently reused; hardcoded base directories mixing artifacts between campaigns; a scanner reading a global constant instead of a per-trial variable and misreporting its own settings. Every one of these produced plausible results before being caught by cross-referencing frozen configuration files against the database.
6. Test-picking, the human kind. Not a code bug — a habit. It is prevented by writing the promotion rule down before running the search, and by treating the test block as a resource you spend rather than a scoreboard you browse.
Combinatorial purged CV: worth it?
Combinatorial purged cross-validation — generating many train/test path combinations from purged blocks to build a distribution of out-of-sample outcomes rather than a single number — is the natural extension, and it is a genuine improvement in statistical power.
Our own pipeline approaches the same robustness problem from a different angle: anchored walk-forward windows with pre-registered criteria, combined with Monte Carlo resampling of trade sequences and neighbourhood testing across parameter space.
A practical checklist
- Order every split chronologically; never shuffle bars.
- Purge every boundary by more than your maximum holding period.
- Add an embargo beyond the purge for long-lookback features.
- Compute features causally — no centred windows, no forward-filled fundamentals, no survivorship-filtered universes.
- Model costs at the venue’s real commissions and mask structural artifacts rather than exploiting them.
- Write the promotion rule before the search runs.
- Rebuild every published number from its frozen artifact before publishing it.
- Make protections fail loudly; a silently disabled safeguard is worse than no safeguard, because it buys false confidence.
FAQ
What is the difference between purging and embargoing?
Purging removes training observations whose labels overlap the test period. The embargo removes an additional margin after the boundary to account for effects that persist beyond label resolution. Purging is mandatory; the embargo is prudent.
Can I use k-fold cross-validation on financial data at all?
Only in purged, chronologically coherent forms. Standard shuffled k-fold on overlapping-label financial data will produce optimistic results reliably enough that you can predict the disappointment.
How wide should the purge gap be?
Wider than the maximum holding period of your labelling scheme, plus the longest feature lookback if that lookback crosses the boundary. When in doubt, wider — the cost is data, and the alternative cost is a false result.
This article describes research methodology. Nothing here is investment advice, and simulated results are not a guarantee of future performance.